Research / Agent systems
Selective tool calls: finding the cost threshold
A carry-detection fixture makes the error–latency trade-off explicit, including the point at which a perfect calculator stops being worthwhile.
Calling a calculator for every addition is accurate in a toy world with a perfect calculator, but may waste latency. Never calling it is fast, but only useful if the internal answer is reliable enough. A tool policy needs a decision criterion that accounts for both errors and the cost of obtaining better information.
Inspect a case
Training utility and runtime utility are different
Toolformer creates candidate API calls, executes them, and retains calls whose results improve prediction of subsequent text according to its filtering criterionKeeping candidate tool calls whose results meet a usefulness criterion.. It then trains on the augmented data. The cost model below is inspired by selective tool use, but it neither implements that training process nor substitutes a runtime threshold for the paper's token-loss criterion. Toolformer, Section 2
The local solver adds the tens digits and adds the units digits modulo ten, accidentally dropping any carry. For 19 + 24, it returns 33 instead of 43. The diagnostic feature is the sum of the units digits, here 13. That feature is not a model confidence score; it is an explicit signal chosen to expose a known failure mode.
The fixture contains fifty pairs: every first number from 10 through 19 and every second number from 20 through 24. Exactly ten pairs require a carry. A policy sends a pair to Python's exact integer addition when the feature is at least a chosen threshold. Otherwise it uses the limited solver.
Locate the useful operating point
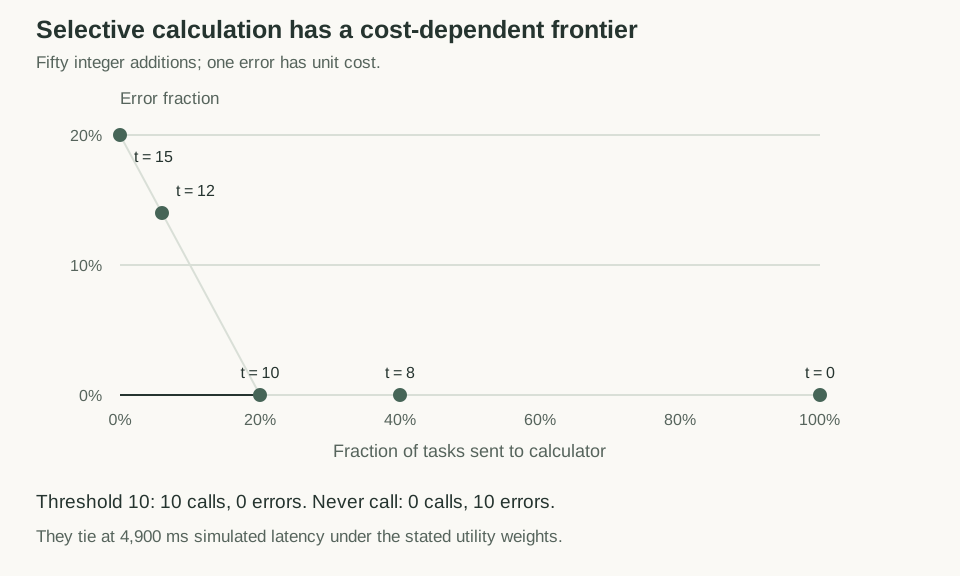
A threshold of zero calls the calculator fifty times and makes no errors. A threshold of ten calls it ten times and also makes no errors. Threshold eight makes twenty calls with the same accuracy, so it is dominated by threshold ten in this fixture. Threshold twelve calls only three times but leaves seven errors. Threshold fifteen makes no calls and leaves ten errors.
These outcomes define an error-versus-call frontier. They do not yet identify the best policy because the relative cost of waiting and answering incorrectly has not been specified. The example objective is error_rate + call_rate × call_cost, with one error assigned unit cost. The call cost contains a fixed 0.02 charge plus 0.2 times simulated latency in seconds.
At a simulated 250 milliseconds per call, the call cost is 0.07. Threshold ten therefore has objective 0 + (10/50) × 0.07 = 0.014, compared with 0.2 for never calling. At five simulated seconds, its objective becomes 0.204, slightly worse than 0.2. That crossover follows from the chosen utility weights, not a measured human preference.
What to measure in a real router
The script does not sleep. Latency is an injected accounting variable, not a wall-clock measurement. Actual tools can fail, return malformed output, or have variable response times. A realistic router must include those outcomes and validate arguments and results, rather than assuming every call repairs an answer.
The apparent perfect threshold is also constructed. It uses knowledge of the solver's defect. If a learned confidence score replaces the feature, calibration becomes central: cases assigned the same confidence should have comparable observed error frequencies on held-out data. A threshold tuned on one arithmetic distribution may not transfer to another.
Solve the break-even point
The extension evaluates every integer threshold from 0 through 15 and retains every operand pair. At threshold ten, all ten known carry errors are repaired with ten calls. Relative to never calling, the benefit is 10/50 error units and the cost is (10/50)c, so indifference occurs at c=1. Substituting c=0.02+0.2L gives L=4.9 seconds.
There is no special timing property at 4.9 seconds. It is the exact consequence of the assigned cost weights and a tool that repairs every affected case. If an error cost doubled, the break-even call cost would double. If the tool sometimes failed to repair an error, the benefit term would shrink. The frontier and the utility weights should be visible separately so either assumption can be changed.
Read the tested Python and recorded output
"""Selective tool calls: finding the cost threshold
Deterministic, standard-library experiment. RESULTS contains the full data.
"""
TASKS = [(a, b) for a in range(10, 20) for b in range(20, 25)]

def limited_solver(a, b):
    tens = 10 * (a // 10 + b // 10)
    units = (a % 10 + b % 10) % 10
    return tens + units

def evaluate(threshold):
    calls = errors = 0
    for a, b in TASKS:
        feature = a % 10 + b % 10
        use_tool = feature >= threshold
        answer = a + b if use_tool else limited_solver(a, b)
        calls += use_tool
        errors += answer != a + b
    return calls, errors

print('n_tasks', len(TASKS), 'latency is simulated, not measured')
for latency_ms in (0, 250, 5000):
    cost_per_call = 0.02 + 0.2 * latency_ms / 1000
    for threshold in (0, 8, 10, 12, 15):
        calls, errors = evaluate(threshold)
        objective = errors / 50 + calls / 50 * cost_per_call
        print(f'ms={latency_ms} threshold={threshold} calls={calls}',
              f'errors={errors} objective={objective:.3f}')
assert evaluate(10) == (10, 0)
assert evaluate(12) == (3, 7)
assert limited_solver(19, 24) == 33


thresholds=[]
for threshold in range(16):
    calls,errors=evaluate(threshold)
    thresholds.append(dict(threshold=threshold,calls=calls,errors=errors,call_rate=calls/50,error_rate=errors/50))
cases=[dict(a=a,b=b,units_sum=a%10+b%10,limited=limited_solver(a,b),truth=a+b,wrong=limited_solver(a,b)!=a+b) for a,b in TASKS]
crossover_ms=round((1-0.02)/0.2*1000, 9)
assert crossover_ms==4900
assert abs((10/50)*(0.02+0.2*crossover_ms/1000)-10/50)<1e-12
RESULTS=dict(tasks=cases,thresholds=thresholds,call_cost_fixed=0.02,call_cost_per_second=0.2,crossover_ms=crossover_ms)
print('Threshold 10 / never-call indifference:',int(crossover_ms),'simulated ms')
Recorded output
n_tasks 50 latency is simulated, not measured
ms=0 threshold=0 calls=50 errors=0 objective=0.020
ms=0 threshold=8 calls=20 errors=0 objective=0.008
ms=0 threshold=10 calls=10 errors=0 objective=0.004
ms=0 threshold=12 calls=3 errors=7 objective=0.141
ms=0 threshold=15 calls=0 errors=10 objective=0.200
ms=250 threshold=0 calls=50 errors=0 objective=0.070
ms=250 threshold=8 calls=20 errors=0 objective=0.028
ms=250 threshold=10 calls=10 errors=0 objective=0.014
ms=250 threshold=12 calls=3 errors=7 objective=0.144
ms=250 threshold=15 calls=0 errors=10 objective=0.200
ms=5000 threshold=0 calls=50 errors=0 objective=1.020
ms=5000 threshold=8 calls=20 errors=0 objective=0.408
ms=5000 threshold=10 calls=10 errors=0 objective=0.204
ms=5000 threshold=12 calls=3 errors=7 objective=0.201
ms=5000 threshold=15 calls=0 errors=10 objective=0.200
Threshold 10 / never-call indifference: 4900 simulated ms