When does a reward bonus change the task an agent learns?
Original exact finite-path calculation; no learned policy, gridworld benchmark, or empirical convergence claim.
This notebook runs the complete saved experiment, checks its assertions, and regenerates the SVG from the computed results. Python 3.10+ and standard-library modules only. Place experiment.py and figure_generation.py beside the notebook. The exact loaded assets are recorded in notebook metadata.
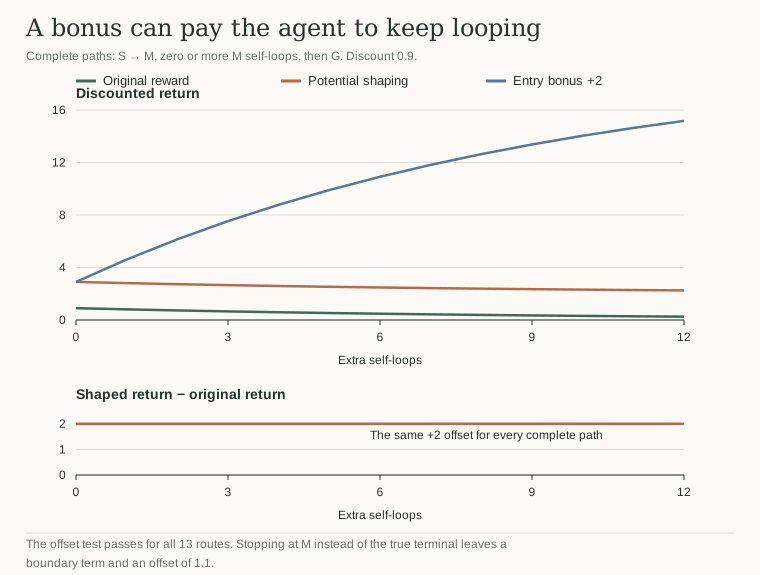
direct: base=1.0, potential=3.0, bonus=1.0
detour: base=0.9, potential=2.9, bonus=2.9
Potential offset for every complete looping path: 2.0
Twelve self-loops: base=0.254187, arbitrary bonus=15.170455
Stopping after S→M leaves boundary term: shaped-minus-base=1.1
Regenerated figure.svg from results.json.
Inspect the saved result
The article's static figure is available before running code. The regenerated figure.svg uses results.json, and every plotted quantity comes from the experiment.
Change an input in experiment.py, rerun both code cells, then compare the saved result and figure.
Python runs locally in this page. Saved results and figures are visible before execution.