Is a safety constraint the same as a large negative reward?
Exact enumeration of a one-step constrained decision and fixed-penalty alternatives; not an implementation of CPO or a real-world safety controller.
This notebook runs the complete saved experiment, checks its assertions, and regenerates the SVG from the computed results. Python 3.10+ and standard-library modules only. Place experiment.py and figure_generation.py beside the notebook. The exact loaded assets are recorded in notebook metadata.
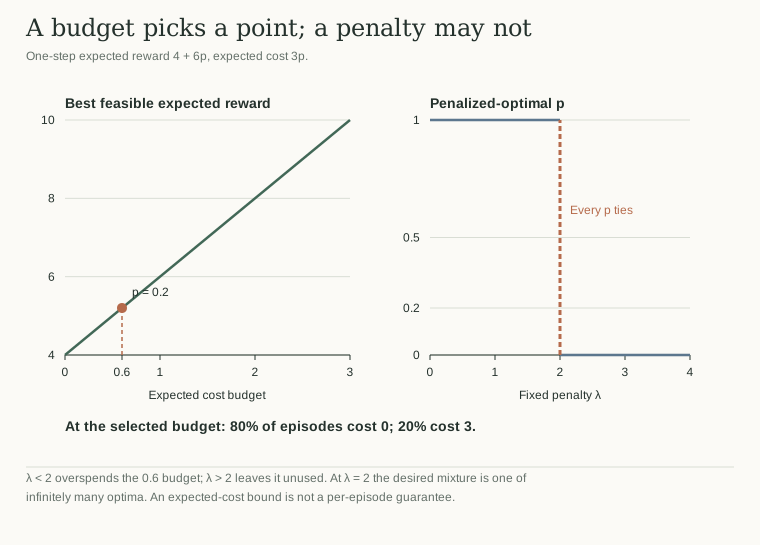
Constrained: p=0.20, reward=5.20, cost=0.60
lambda=0.5: optimal p range [1.00, 1.00]
lambda=1.5: optimal p range [1.00, 1.00]
lambda=2.0: optimal p range [0.00, 1.00]
lambda=3.0: optimal p range [0.00, 0.00]
At constrained optimum, cost-3 episodes occur with probability 0.20
Budget sweep: each extra cost unit buys 2 reward units until budget 3.
At budget 0.6, the expected-cost-optimal policy still exceeds that budget in 20% of episodes.
Regenerated figure.svg from results.json.
Inspect the saved result
The article's static figure is available before running code. The regenerated figure.svg uses results.json, and every plotted quantity comes from the experiment.
Change an input in experiment.py, rerun both code cells, then compare the saved result and figure.
Python runs locally in this page. Saved results and figures are visible before execution.