Why would a controller be rewarded for staying unpredictable?
Exact finite-action entropy optimization for hand-specified values; not SAC training or a continuous-control benchmark.
This notebook runs the complete saved experiment, checks its assertions, and regenerates the SVG from the computed results. Python 3.10+ and standard-library modules only. Place experiment.py and figure_generation.py beside the notebook. The exact loaded assets are recorded in notebook metadata.
alpha=0.05 p=[0.982, 0.018, 0.0]
  reward=0.9964 entropy=0.0901 objective=1.0009
alpha=0.20 p=[0.7275, 0.2676, 0.0049]
  reward=0.9416 entropy=0.6103 objective=1.0636
alpha=1.00 p=[0.4573, 0.3744, 0.1682]
  reward=0.7569 entropy=1.0255 objective=1.7824
Reward/temperature rescaling check: passed
All 15,453 simplex candidates satisfy J(p*)−J(p) = alpha × KL(p || p*) within 1e−12.
Regenerated figure.svg from results.json.
Inspect the saved result
The article's static figure is available before running code. The regenerated figure.svg uses results.json, and every plotted quantity comes from the experiment.
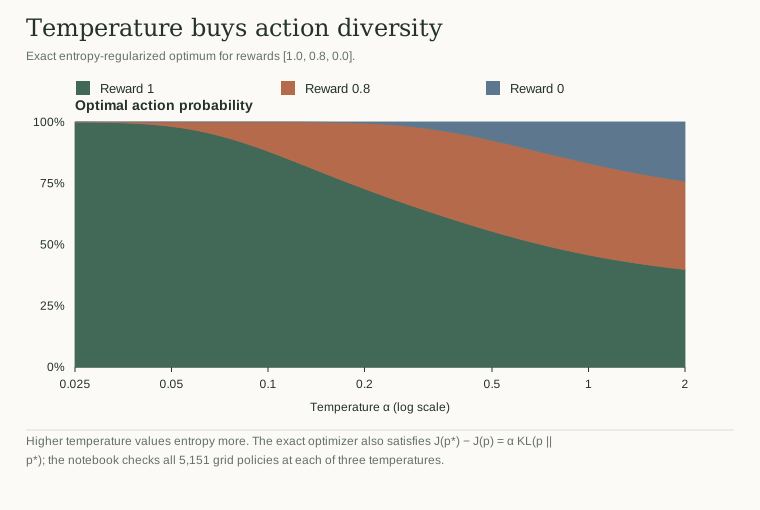
Change an input in experiment.py, rerun both code cells, then compare the saved result and figure.
Python runs locally in this page. Saved results and figures are visible before execution.