When is it worth separating prompt processing from token generation?
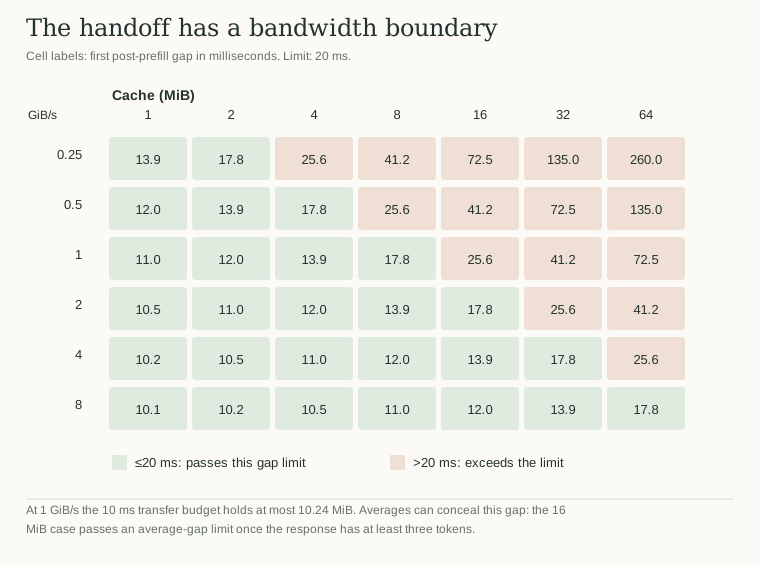
Original CPU latency-budget model. Prefill emits token one; transfer precedes token two. Uses maximum gap, not DistServe's measured goodput.
This notebook runs the complete saved experiment, checks its assertions, and regenerates the SVG from the computed results. Python 3.10+ and standard-library modules only. Place experiment.py and figure_generation.py beside the notebook. The exact loaded assets are recorded in notebook metadata.
cache=4 MiB: transfer=3.906 ms, handoff_gap=13.906 ms, compliant=True
cache=16 MiB: transfer=15.625 ms, handoff_gap=25.625 ms, compliant=False
transfer_budget=10.0 ms
At 1 GiB/s, maximum passing cache = 10.24 MiB under the 10 ms transfer budget.
16 MiB handoff: average gap passes with >=3 total output tokens, but the maximum gap remains 25.625 ms.
Regenerated figure.svg from results.json.
Inspect the saved result
The article's static figure is available before running code. The regenerated figure.svg uses results.json, and every plotted quantity comes from the experiment.
Change an input in experiment.py, rerun both code cells, then compare the saved result and figure.
Python runs locally in this page. Saved results and figures are visible before execution.